open-pryv.io
Open Pryv.io v2.0.0-rc.2

Personal data & privacy management — open source

Release-candidate warning: This is the v2 release candidate of Open Pryv.io. It is under active stabilization and not yet recommended for production workloads. For the last stable v1 release, see the
release/1.9.3branch.
What is Pryv.io
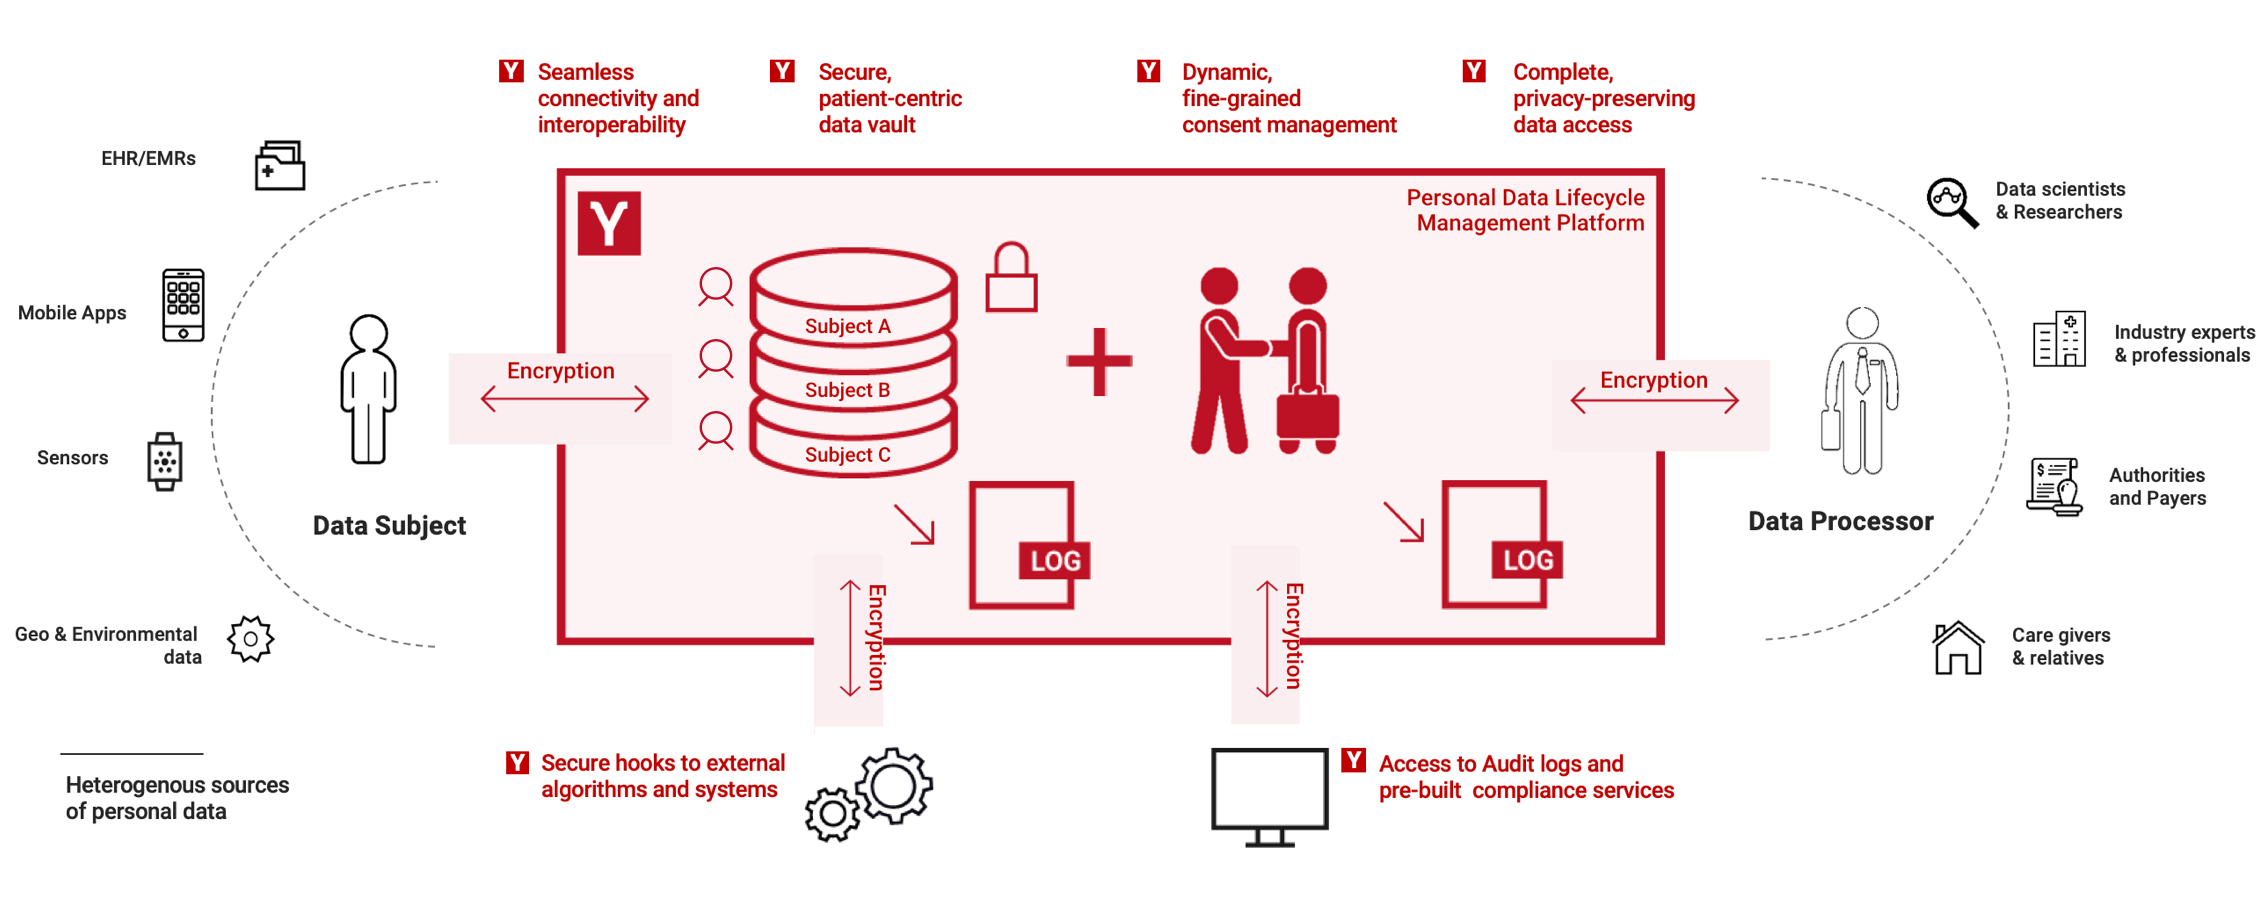
Pryv.io is a data privacy management solution designed to collect, store and share personal data in compliance with privacy regulations (GDPR, HIPAA, LPD). It provides a RESTful API for managing user data organized into streams (hierarchical categories) and events (timestamped data points), with fine-grained access controls and real-time notifications.
Pryv.io serves as the backend for applications in health, quantified self, smart cities, and any domain requiring data sovereignty and consent management. Each user’s data is isolated and access-controlled independently.
What’s new in v2
- Pluggable storage engines — PostgreSQL (default), SQLite, InfluxDB, filesystem, S3, rqlite. Engines are plugins under
storages/engines/with manifest-driven configuration. A full-PostgreSQL diskless shape (optionally with S3 attachments) keeps every durable byte off the local filesystem. - Unified master process — single
bin/master.jsmanages N API workers + M HFS workers + optional previews worker. Single Docker image replaces multi-container orchestration. - Built-in user registration — no external service-register needed. Registration fully self-contained via PlatformDB.
- Built-in MFA — two-factor authentication as
mfa.*API methods: an authenticator app (TOTP, RFC 6238), enabled by default and working out of the box, or SMS (opt-in). - rqlite for PlatformDB — distributed platform storage for single- and multi-core deployments with Raft consensus.
- Multi-core deployments — HTTP 421 wrong-core routing, DNS-based or DNSless topology, platform-config-snapshot hash comparison for drift detection.
- Backup, restore & integrity — engine-agnostic backup to JSONL+gzip, per-user integrity verification with SHA-256 hashes.
- Optional observability — telemetry built from a fixed allow-list (per-method call counts, durations, error counts, sanitized stack traces) and shipped over OTLP/HTTP, so any OTLP-ingesting backend works, including a collector you host yourself. No third-party agent runs in the process. Opt-in, cluster-wide config via PlatformDB (auth headers AES-256-GCM encrypted at rest). Operator guide: Observability.
For the full v2 change history, see CHANGELOG-v2.md (API-facing) and CHANGELOG-v2-back.md (internal).
Quick start — single-core with Docker
The Docker image ships an interactive install wizard. Pick (or create) the directory where your install should live, run the wizard, then start with the generated launcher:
mkdir -p /opt/pryv && cd /opt/pryv
docker run -it --rm -v "$(pwd):/app/pryv" pryvio/open-pryv.io:2.0.0-rc.2 init
./run-pryv.sh
Test it:
curl http://localhost:3000/   # adjust to the public URL you chose in the wizard
# {"meta":{"apiVersion":"..."},"cheersFrom":"Pryv API","learnMoreAt":"https://pryv.github.io/"}
INSTALL.md is the single source of truth for installation — wizard details, hand-crafted configs, TLS strategies, nginx fronting, Dokku, the diskless shape (PostgreSQL + S3 — or PostgreSQL only for low attachment volumes), and v1 → v2 upgrades.
Native installation
Prerequisites: Node.js 24.x below 24.19.0 (see INSTALL.md: later 24.x releases abort on SQLite), PostgreSQL 14+ (or SQLite — bundled), just.
just setup-dev-env    # setup local file structure + PostgreSQL + rqlite
just install          # install node modules
just start-master     # start in cluster mode
See INSTALL.md for detailed instructions.
Multi-core deployment
See SINGLE-TO-MULTIPLE.md for the full upgrade procedure from single-core to multi-core.
Email integration
Transactional emails ship with two delivery paths — pick one via services.email.method:
in-process(recommended) — renders Pug templates inside the api-server workers; templates live in PlatformDB (rqlite, cluster-wide). Templates for welcome, password-reset, email-verification and registration-code mails ship with the server and are seeded into PlatformDB on first boot; override withtemplatesRootDiror edit them afterwards withbin/mail.js. Edit without a deploy viabin/mail.jsorPOST /system/admin/mail/*.microservice— the legacy external service-mail process bound to127.0.0.1:9000on each core. Default today for back-compat.
services:
  email:
    enabled: { welcome: true, resetPassword: true }
    method: in-process
    defaultLang: en
    from: { name: 'Pryv Lab', address: 'no-reply@example.com' }
    smtp: { host: smtp.example.com, port: 587, auth: { user: '...', pass: '...' } }
    # templatesRootDir: /opt/...   # optional: your own Pug set instead of the bundled one
Full operator guide: Email configuration.
For local development convenience with the legacy microservice:
just mail-dev # clones and starts service-mail locally
Data migration from v1
To migrate data from a v1 (open-pryv.io 1.x) deployment to v2, use dev-migrate-v1-v2. The migration tool handles schema differences between v1 and v2 storage formats.
Architecture
node bin/master.js
  |
  +-- Master process
  |   +-- rqlited (PlatformDB, Raft consensus)
  |   +-- TCP pub/sub broker (:4222)
  |   +-- Process manager (fork/monitor workers)
  |
  +-- N x API Worker (cluster, shared :3000)
  |   +-- API routes (events, streams, accesses, auth, ...)
  |   +-- Socket.IO (real-time notifications)
  |   +-- Webhooks subscriber (in-process)
  |
  +-- M x HFS Worker (cluster, shared :4000, 0 = disabled)
  |   +-- Series routes (high-frequency data)
  |   +-- Metadata updater (in-process)
  |
  +-- 0-1 x Previews Worker (:3001, lazy/optional)
Storage engines
| Engine | Storage types | Status |
|---|---|---|
| PostgreSQL | base, dataStore, series, audit, platform (diskless single-core), file (attachments — low volume only) | Production (default) |
| SQLite | base, dataStore, series, audit (per-user files) | Production (alternative) |
| rqlite | platform (single- and multi-core) | Production |
| Filesystem | file (attachments) | Production (default for file) |
| S3 | file (attachments — AWS S3, MinIO, Ceph RGW, …) | Production |
| InfluxDB | series (HFS) | Production |
Project structure
open-pryv.io/
+-- bin/                    # Entry points
|   +-- master.js           # Cluster master (N API workers)
|   +-- backup.js           # Backup/restore CLI
|   +-- integrity-check.js  # Data integrity verification CLI
+-- components/             # Application components (npm workspaces)
|   +-- api-server/         # Main API server
|   +-- hfs-server/         # High-frequency series server
|   +-- previews-server/    # Image previews
|   +-- business/           # Business logic
|   +-- storage/            # Storage abstraction layer
|   +-- mall/               # Data access layer
|   +-- cache/              # Caching
|   +-- messages/           # TCP pub/sub
|   +-- audit/              # Audit logging
|   +-- middleware/         # Express middleware
|   +-- webhooks/           # Webhook business logic (runs in api-server)
|   +-- test-helpers/       # Test infrastructure
+-- storages/               # Plugin system (npm workspace)
|   +-- engines/            # postgresql, sqlite, filesystem, s3, influxdb, rqlite
|   +-- interfaces/         # Formal contracts per storage type
+-- config/                 # Default and environment configs
+-- Dockerfile              # Single-image Docker build
+-- justfile                # Development commands
Testing
just test all                     # all components (PostgreSQL — default since v2)
just test api-server              # single component
just test-sqlite all              # SQLite mode (alternative engine)
just test-parallel all            # parallel file execution
just clean-test-data              # reset test databases
Documentation
For LLM coding agents
If you are an AI coding assistant (Claude Code, Cursor, Copilot, etc.) bootstrapping against this repo, start with AGENTS.md — a fast-orientation guide to the tree, entry points, storage-engine plugin system, and things not to touch without asking.
Sponsors
Open Pryv.io development is supported by:

The Health Data Safe Foundation empowers individuals to securely collect, manage, control, and share their health data on their own terms.
Want to support the project? Become a sponsor.